The science behind SciVeri-Bench
Can AI agents verify good science?
A deploy-first, scientist-driven benchmark: our motivation, three scientific verification tasks, and task collection through the Scientist-in-the-Loop harness.
The current research agents are Claude Code (Opus 5.5), Codex (GPT-6-Astra), OpenScience (GPT-6-Astra). The original overview below retains an earlier agent lineup. See the current execution setup.
On this page
Young-Jun Lee, Seungone Kim, Jinheon Baek, Soojung Yang, Yoonho Lee, Dongyeop Kang
Through this work, we aim to answer the question:
Can AI agents evaluate what constitutes good science as well as scientists can?
Current agent benchmarks rely on static evaluation#
Until last year, benchmarks based on competition problems, such as IMO, focused on how well reasoning models could solve given problems through deep reasoning, and performance on many of these benchmarks had largely saturated. As the agentic AI market has grown, a large number of agent benchmarks have emerged, including long-horizon agent benchmarks such as GAIA and tau3-bench; agentic coding benchmarks such as SWE-Bench Verified, TerminalBench 2.1, DeepSWE, and FrontierCode; and agentic computer-use benchmarks such as OSWorld 2.0. These recent benchmarks all evaluate agent capabilities in a static way. Some use deterministically verifiable scores as their headline metrics, while others use fixed rubrics created by domain experts and score outcomes through an LLM-as-a-Judge approach.
Science is alive, yet its evaluation mostly remains static.#
More recently, the rise of AI for Science has led to many proposed science benchmarks, but these also continue to adopt static evaluation methods: a single scalar headline metric based on a verifiable function or a scientist-verified rubric. Examples include PaperBench and NatureBench for paper reproduction; MLE-Bench for AI/ML engineering; FrontierScience for proposing follow-up research directions; and LifeSciBench, TerminalBench-Science, and FrontierPhysics for expert-curated scientific problems.
However, static evaluation metrics alone are not sufficient to verify whether an AI agent’s output constitutes good science. Many scientific problems, such as causal mechanism discovery, are open-ended: a satisfactory solution has yet to be discovered, and there is no reference answer that defines what constitutes good science [1,2]. For such problems, no one knows what a novel discovery or good science will look like before experiments are conducted. Therefore, static and fixed evaluation metrics, even with rubrics curated by scientists, are not sufficient to verify good science.
How do scientists verify good science?#
Over time, as experiments are conducted and results accumulate, domain scientists (1) identify weaknesses or gaps in the experimental results, (2) use these observations to progressively refine their criteria for what constitutes good science in the context of those experiments, and (3) judge which results are better based on their experience and intuition (e.g., whether earlier results were better or which of two experiments produced better results).
However, most existing science benchmarks have focused on agents’ problem-solving capabilities rather than their verification capabilities. Although it is important to evaluate how well AI agents can solve scientific problems compared with scientists, it is equally important to evaluate how well they can match scientists in verifying whether an outcome constitutes good science or a novel discovery.
Contributions#
- We propose SciVeri-Bench, a deploy-first, scientist-driven benchmark that evaluates AI agents’ ability to perform scientific verification as human domain scientists do on open-ended, novel scientific tasks.
- Our benchmark evaluates AI agents’ capabilities on three tasks: scientist rubric generation, scientist critique generation, and scientist taste evaluation.
- To construct our benchmark, we introduce a Scientist-in-the-Loop harness designed to support effective collaboration between domain scientists and AI researchers, with all communication taking place on the OpenReview platform. Through this platform, scientists can propose and review tasks, run AI agents, and verify the agents’ outputs on those tasks. This provides a natural starting point for scientists who want to try AI agents.
🌟🌟🌟 All intellectual property rights to the outcomes generated by the agent for a proposed task will belong to the task proposer and reviewers. We will not claim ownership of these outcomes. You may use them to submit a paper to a Nature-family journal, and you are not required to include members of the co-lead team as co-authors.
SciVeri-Bench: Benchmarking AI Agents for Scientific Verification#
Guidelines for Task Collection: [Guideline] Track 4: SciVeri-Bench Task Proposal
Benchmark Design Principle#
One Interface for Collaboration. To create open-ended and novel scientific tasks, we consider the following points:
- Without help from domain scientists, it is hard to create open-ended and novel tasks. In addition, without multiple rounds of proposing and reviewing tasks, it will be difficult to come up with good open-ended and novel tasks.
- Even if domain scientists initially propose a task, it is very challenging for them to develop a good rubric for evaluating what constitutes “good” science without running experiments. This is because an understanding of what constitutes “good” science is learned through the experience of running scientific experiments.
- Domain scientists are not familiar with using AI agents or implementing code. Therefore, if we place too much responsibility for running agents on scientists, it may become a burden and make it difficult to obtain high-quality tasks. We need to enable domain scientists to do their best and concentrate on creating good open-ended and novel tasks that pose important scientific questions.
Therefore, we believe that when collecting scientific tasks from domain scientists, we need to provide an environment where AI researchers and domain scientists can interact while each group carries out its role as effectively as possible in its own setting. For example, AI researchers can run AI agents on proposed tasks in a computing environment, while domain scientists can think about and propose good scientific tasks wherever they feel comfortable, such as their lab or home. The two groups communicate through a single interface, allowing each to focus on its respective role. For the interface, we select OpenReview.
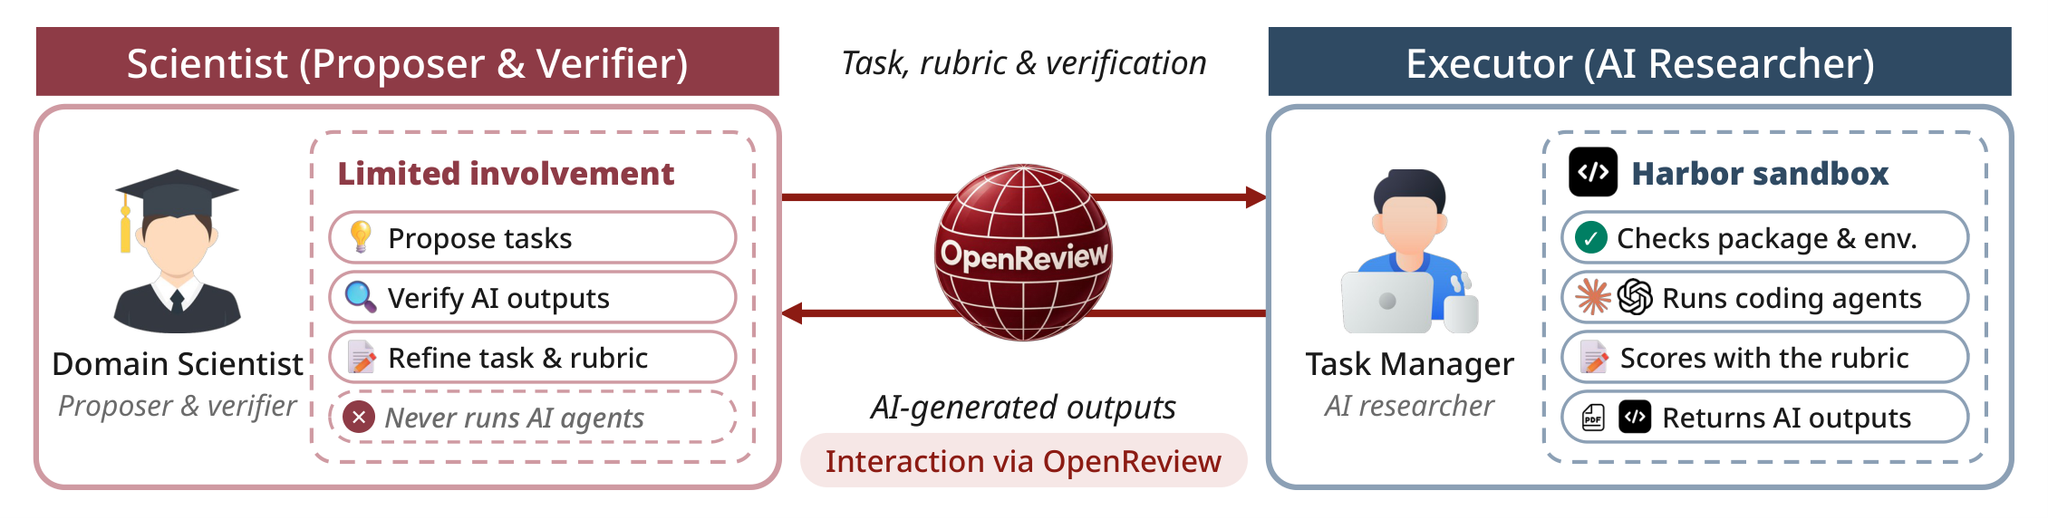
Scientists familiar with AI agents might run agents in their own environments and focus only on obtaining low scores (= challenging tasks), potentially at the expense of proposing truly good open-ended tasks. To prevent this, we separate the proposer and verifier, similar to the sandbox environment in Harbor. Scientists serve in two roles: proposers and verifiers. Their involvement is limited to proposing tasks, verifying the AI agent’s outputs, and refining their tasks and evaluation rubrics based on feedback from the executor (e.g., AI-generated outputs). These interactions take place through OpenReview, as illustrated in the figure below.
Open-Ended and Novel Tasks. When collecting tasks for our benchmark, we use the following minimum criteria to define “open-ended” and “novel.” An open-ended task is one whose outcomes cannot be adequately evaluated using a single scalar score. For novelty and frontier relevance, we consider whether the task itself is significant enough to merit publication in a Nature-family journal.
Verification Tasks in SciVeri-Bench#
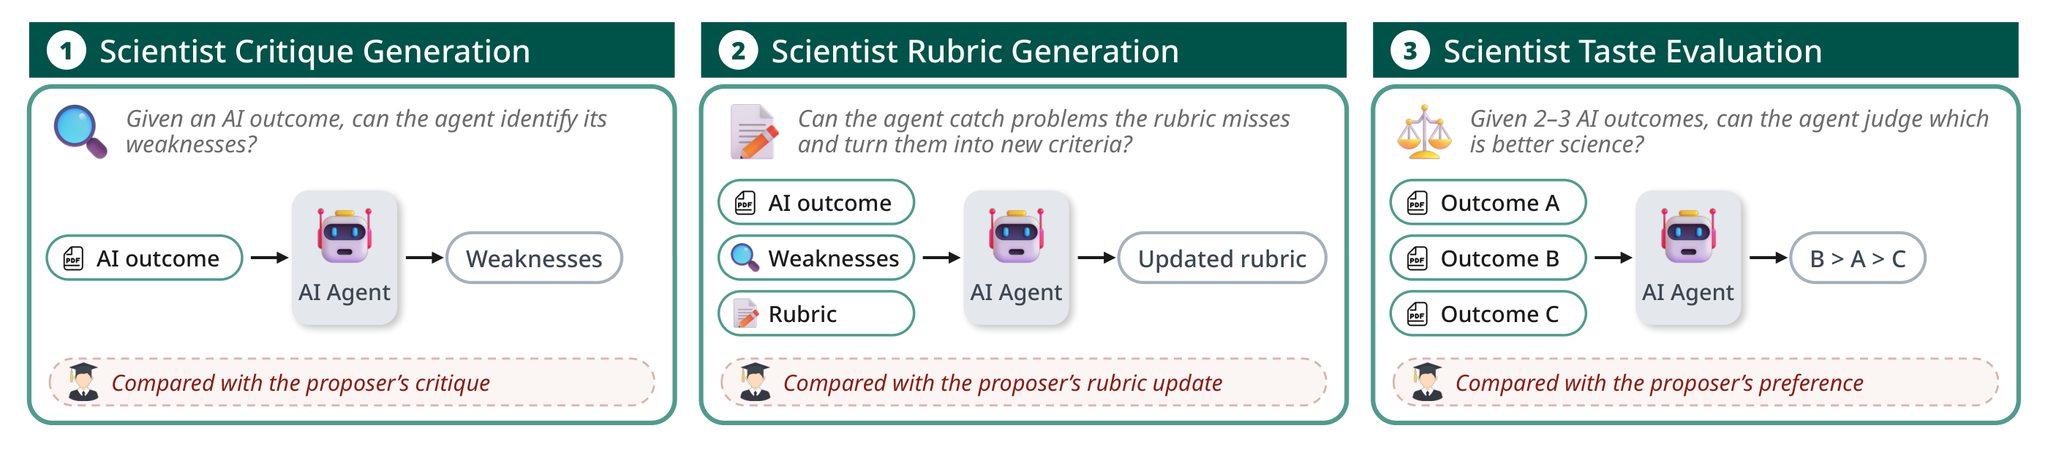
- Scientist Critique Generation: Given an AI outcome, can an evaluator identify its weaknesses?
- Scientist Rubric Generation: Given an AI outcome and an existing rubric, can an evaluator identify problems in the outcome that the rubric does not yet cover? If a new problem appears in the AI outcome, can the evaluator turn it into a rubric criterion?
- Scientist Taste Evaluation: Given 2~3 AI outcomes, can an evaluator judge which one represents better science than the others?
Task Collection through Scientist-in-the-Loop Harness#
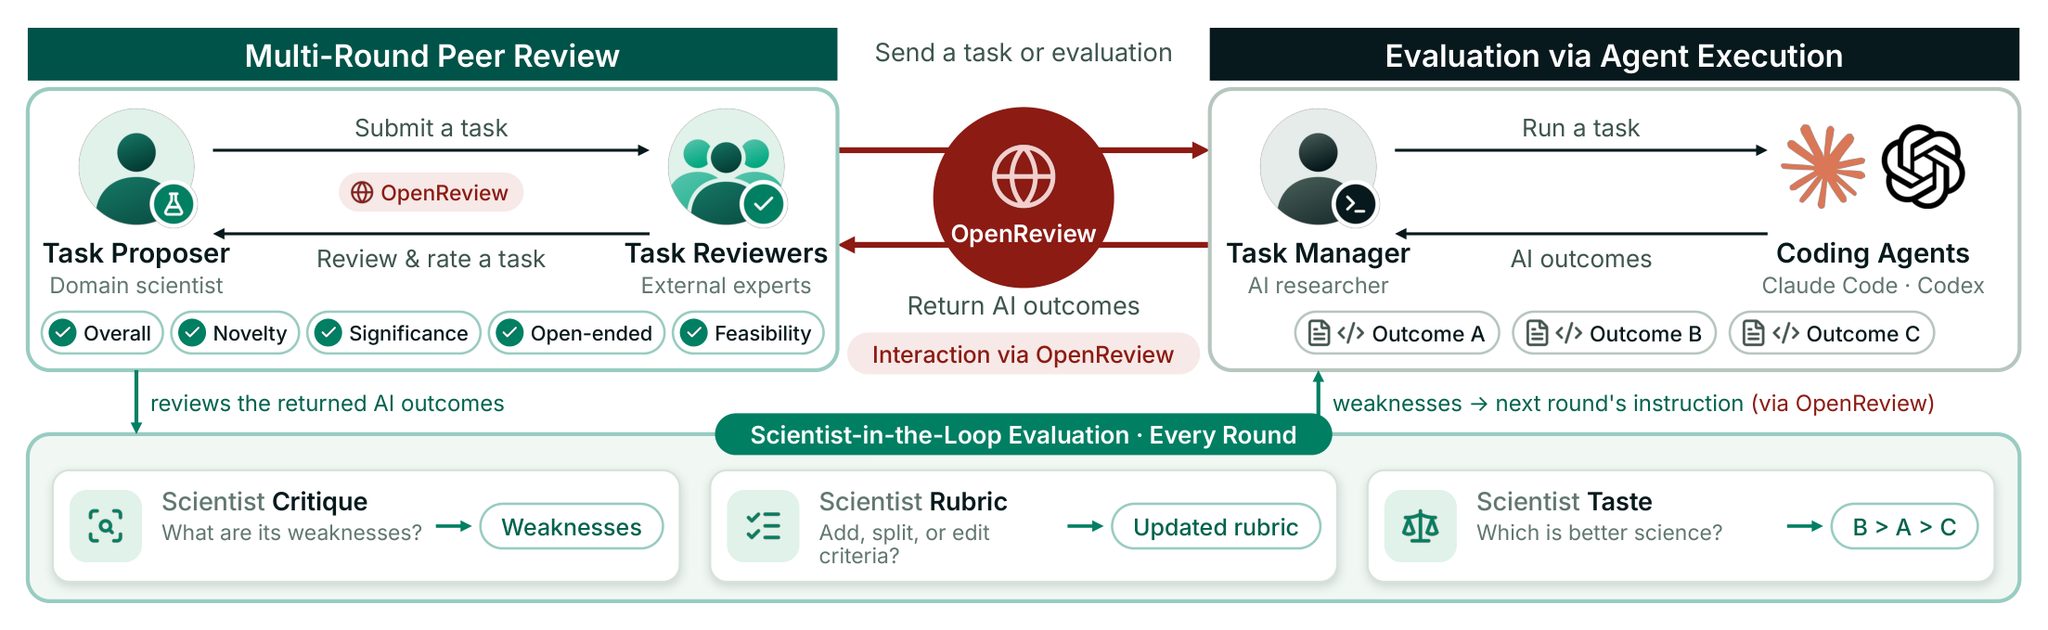
We collect open-ended and novel tasks from domain scientists through a “scientist-in-the-loop” harness. Our scientist-in-the-loop harness is fully automated for AI researchers and provides an environment where domain scientists can focus entirely on creating good tasks. Moreover, all communication between domain scientists and AI researchers can take place on OpenReview. In other words, scientists only need to check SciVeri-Bench 2026 Internal Review.
When collecting tasks, it is essential to solicit open-ended tasks whose outcomes cannot be adequately evaluated using a single scalar score. The problems addressed by these tasks must also be novel and at the research frontier.
What qualifies as “Novel & Frontier”? Whether the task itself is significant enough to merit publication in a Nature-family journal.
We intend to give contributors flexibility when proposing tasks. Examples include a problem they would like an AI agent to solve, a problem they consider difficult or novel in their field, follow-up research on a paper published in a Nature-family journal or a top conference within the past two years, or ongoing research in their lab. However, every task must be both open-ended and novel.
The overview of our “scientist-in-the-loop harness” is provided below.
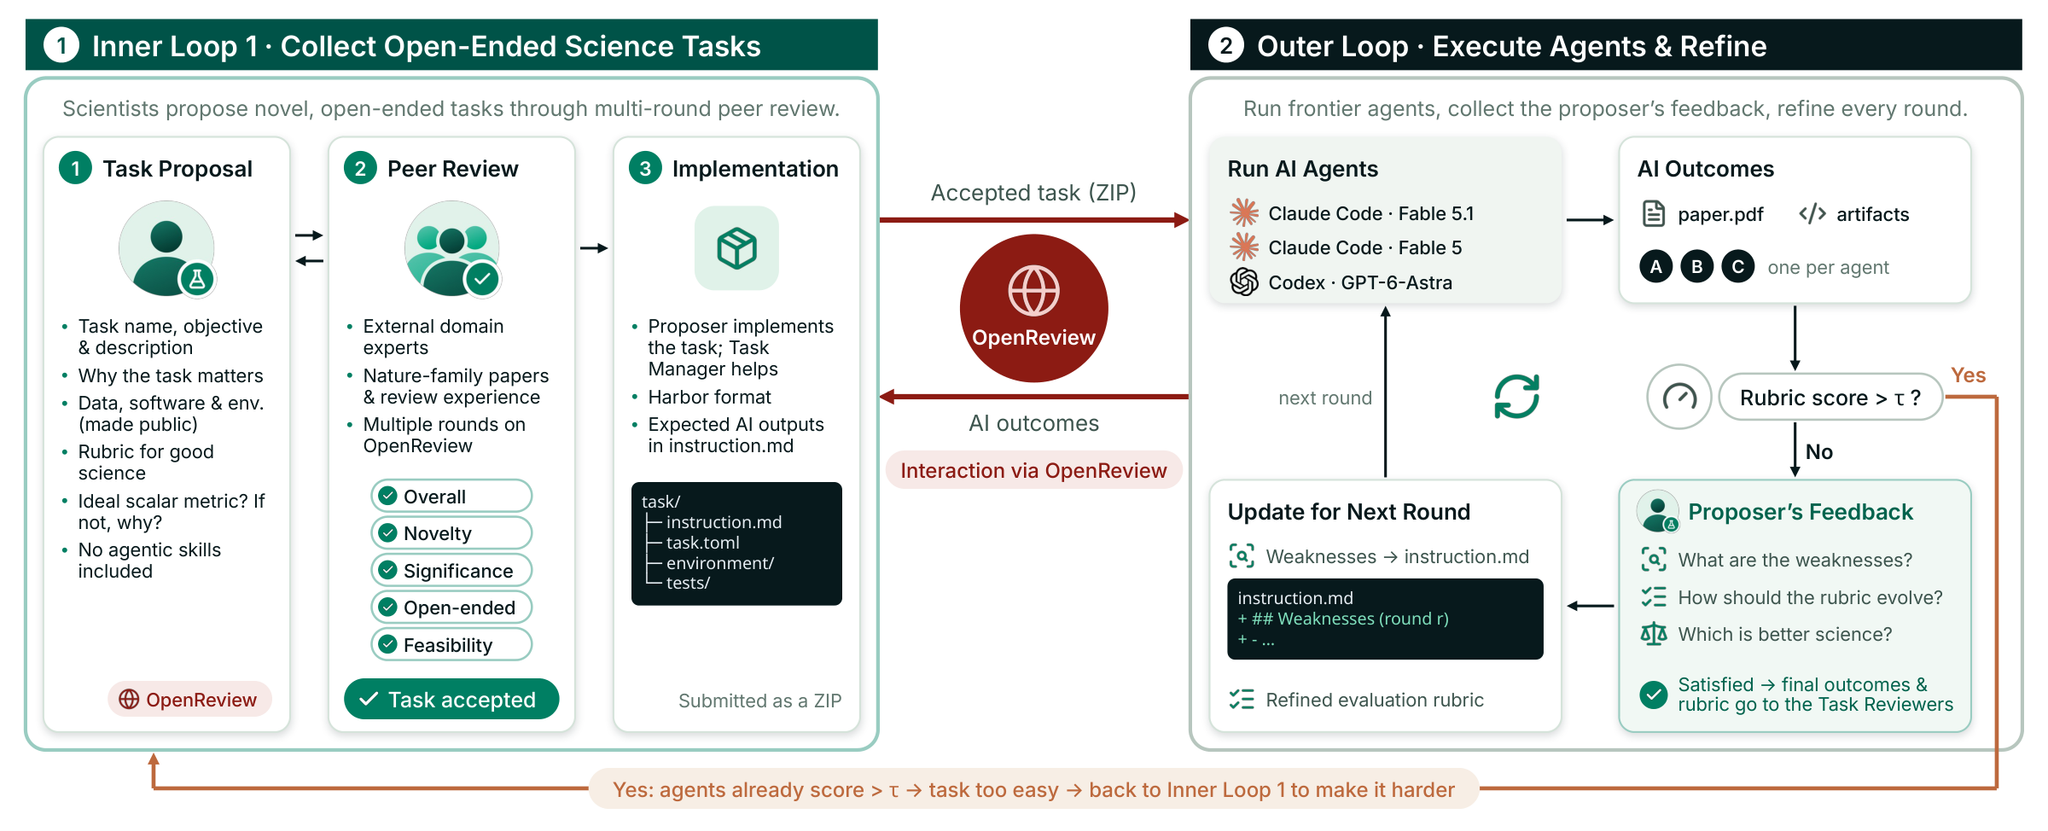
Step 1: Collecting Open-Ended Science Tasks through Multi-Round Peer Review#
The task proposer submits a task with the following information:
- Task name
- Task objective and description
- Why the task is important
- Data, software, and environment required to execute the task
- If the task requires custom simulators or software developed in the proposer’s lab, the proposer must agree to make them publicly available.
- If the task requires data that are not publicly available, the proposer must agree to make those data publicly available.
- Agentic skills must not be included in the task submission.
- An evaluation rubric defining what constitutes good science for the proposed task
- Do you think there exists an ideal metric (e.g., a scalar score) that can well represent the quality of AI outcomes on your proposed task? If not, why?
After submission, the SciVeri-Bench team assigns three reviewers with expertise relevant to the task, following a conference-style process and checking conflicts of interest. Task proposers do not nominate reviewers. Assigned reviewers should:
- Have research experience in the scientific field relevant to the proposed task
- Have one or two publications in Nature-family journals or at top-tier conferences
- Have completed at least one or two peer reviews for such journals or conferences
The three assigned reviewers independently assess whether the proposed task is open-ended, novel, scientifically meaningful, and potentially suitable for publication in a Nature-family journal. The proposer responds to all three reviewers through multiple rounds of discussion in OpenReview. The team manages replacements if a reviewer cannot participate.
After considering all three final reviews and the proposer's responses, the SciVeri-Bench team records its acceptance or revision decision in OpenReview. Once the team accepts the task, the proposer implements it and submits a ZIP file through OpenReview. If the proposer is unfamiliar with code implementation, the task manager helps implement the code. The task structure follows the Harbor format.
When implementing the task, specify the expected AI outputs in
instruction.md. These may vary by task and could include task-specific artifacts and apaper.pdf.
Step 2: Executing AI Agents on the Proposed Task#
In this step, we run AI agents on the proposed task over multiple rounds to identify weaknesses in their outcomes, refine the evaluation rubric accordingly, and have the task proposer select their preferred AI outcome. This process forms another inner loop.
We use three frontier agents: Claude-Code Fable 5.1, Claude-Code Opus 5, and Codex GPT-6-Astra. In the first round, we run these agents on the proposed task to obtain AI outcomes, including task-specific artifacts and a paper. We then evaluate these outcomes using the initial rubric. If performance exceeds a certain threshold (to be determined empirically), we exit this inner loop and return to Inner Loop 1, where the task proposer and assigned reviewers refine the proposed task to make it more challenging based on the feedback.
Otherwise, we continue by showing the task proposer the outcomes from the three agents and conducting a survey with the following questions:
- Are you satisfied with the current AI outcomes? If not, what do you consider their weaknesses? → For Scientist Critique Generation
- What problems do you see, and how should they be reflected in the rubric? Should existing criteria be broken down, edited, or supplemented with new criteria? → For Scientist Rubric Generation
- Among the two or three AI outcomes, which appears to have produced better findings or conducted more scientifically meaningful experiments? → For Scientist Taste Evaluation
When running the agents in the next round, we include the weaknesses identified in the previous round’s outcomes in instruction.md.
Once the scientist determines that no further work is needed, we send the final AI outcomes and rubric to the three assigned task reviewers, who assess the quality of both.
Note that even if the iterative process saturates quickly, this is still acceptable, as our benchmark aims to understand how verification itself can be verified.
[1] Cornelio, Cristina, et al. "The need for verification in AI-driven scientific discovery." arXiv preprint arXiv:2509.01398 (2025).
[2] Ríos-García, Martiño, et al. "AI scientists produce results without reasoning scientifically." arXiv preprint arXiv:2604.18805 (2026).